👋 About Me
Hi, I am Dingdong Wang (王丁冬).
I am a Ph.D. candidate in Systems Engineering and Engineering Management (SEEM) at 🇭🇰 The Chinese University of Hong Kong (CUHK), advised by Prof. Helen Meng (Fellow of IEEE and ISCA). My research focuses on speech-native and multimodal foundation models that can hear, understand, reason, and interact. Concretely, I work on speech representation, instruction-following, spoken language reasoning, and end-to-end dialogue.
If you are interested in collaboration, feel free to drop me an email.
I am currently looking for full-time job opportunities and am broadly interested in multimodal LLMs, audio processing, agentic AI, and world models.
🎓 Education
- Supervisor: Prof. Helen Meng (Fellow of IEEE and ISCA).
- Research area: Speech and multimodal large language models, with a focus on spoken language understanding, reasoning, and end-to-end dialogue.
- Major: Statistics.
- Awards: Department of Statistics Scholarship; Dean's List.
🔥 News
- [2026/08] 3 papers are accepted by EMNLP 2026.
- [2026/05] The survey of audio reasoning in multimodal foundation models is released on arXiv.
- [2026/04] One paper accepted to ICML 2026.
- [2026/02] EmotionThinker selected for 🏆 Oral Presentation.
- [2026/01] Two first-author papers, MMSU and EmotionThinker, accepted to ICLR 2026.
- [2025/12] Wan-Move tops Hugging Face Weekly Papers (Dec 7–13).
- [2025/09] Wan-Move accepted to NeurIPS 2025.
- [2025/08] One first-author paper, Speech Discrete Tokens or Continuous Features? accepted to EMNLP 2025 Main Conference.
- [2025/05] One first-author paper, InSerter accepted to ACL 2025 Main Conference.
- [2025/05] SocialCC and Language-Codec accepted to ACL 2025 Main Conference.
- [2024/09] SimpleSpeech wins the 🏆 Best Student Paper Award at INTERSPEECH 2024.
📝 Selected Publications (Full List)
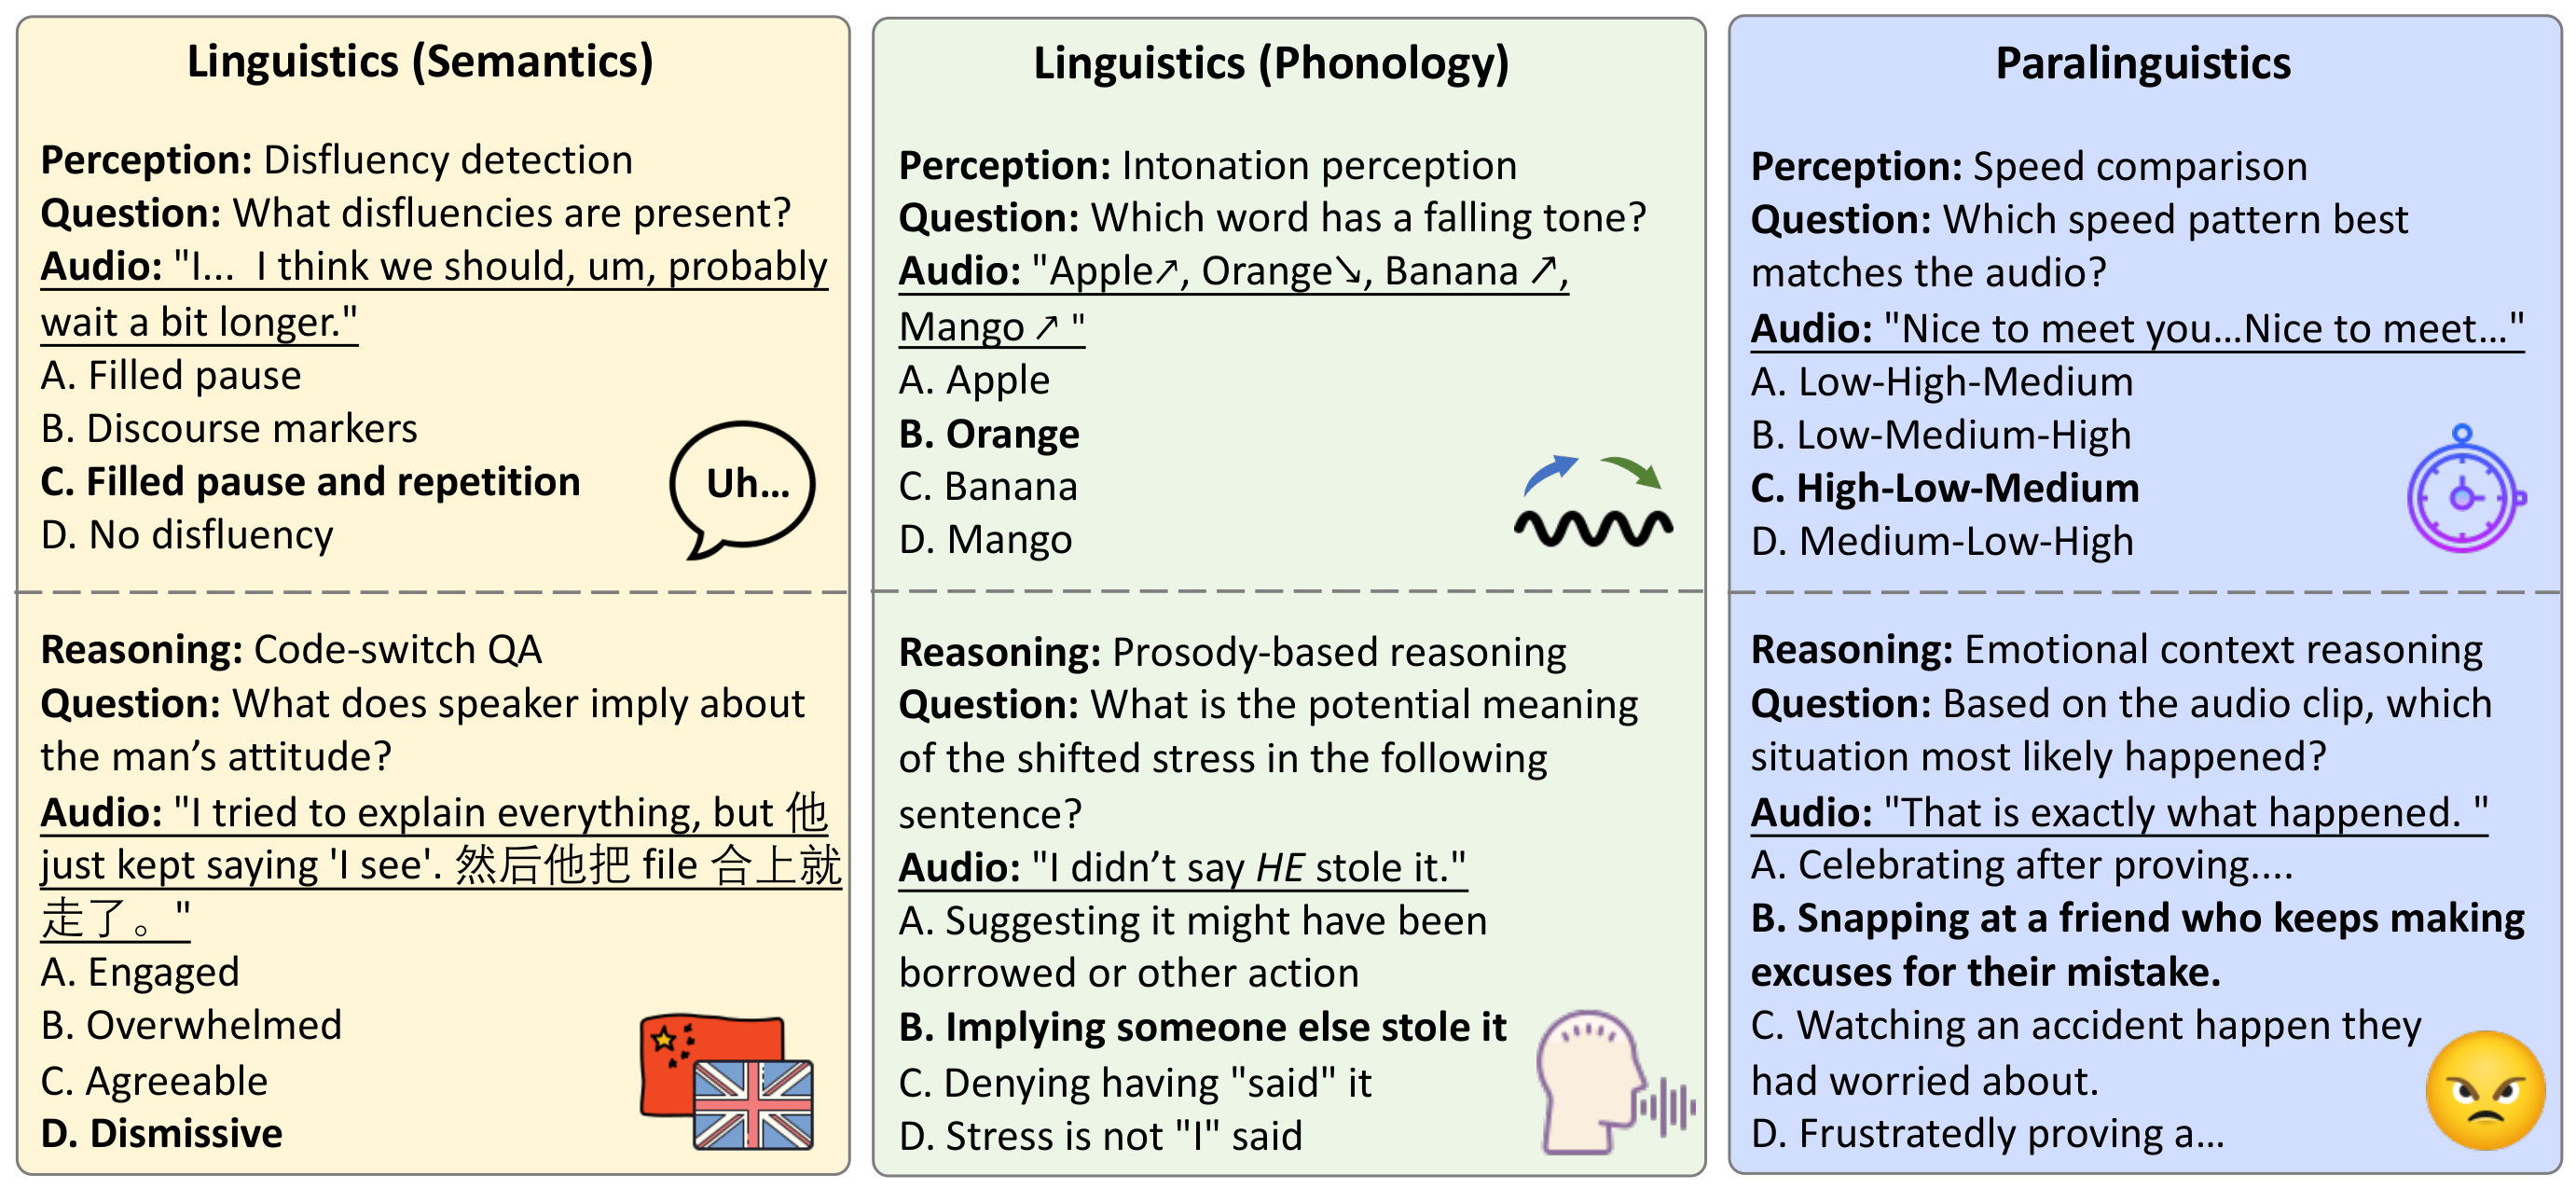
MMSU: A Massive Multi-Task Spoken Language Understanding and Reasoning Benchmark
- 5,000 QA triplets, 47 tasks: spans 24 perception + 23 reasoning tasks grounded in linguistic theory (phonetics, prosody, rhetoric, syntactics, semantics, paralinguistics).
- Industry-adopted: used to benchmark flagship MultimodalLLMs including Audio Flamingo 3 / Audio-Visual Flamingo, Qwen2.5-Omni / Qwen3-Omni, Seed-Audio 1.0, and MiMo-Audio.
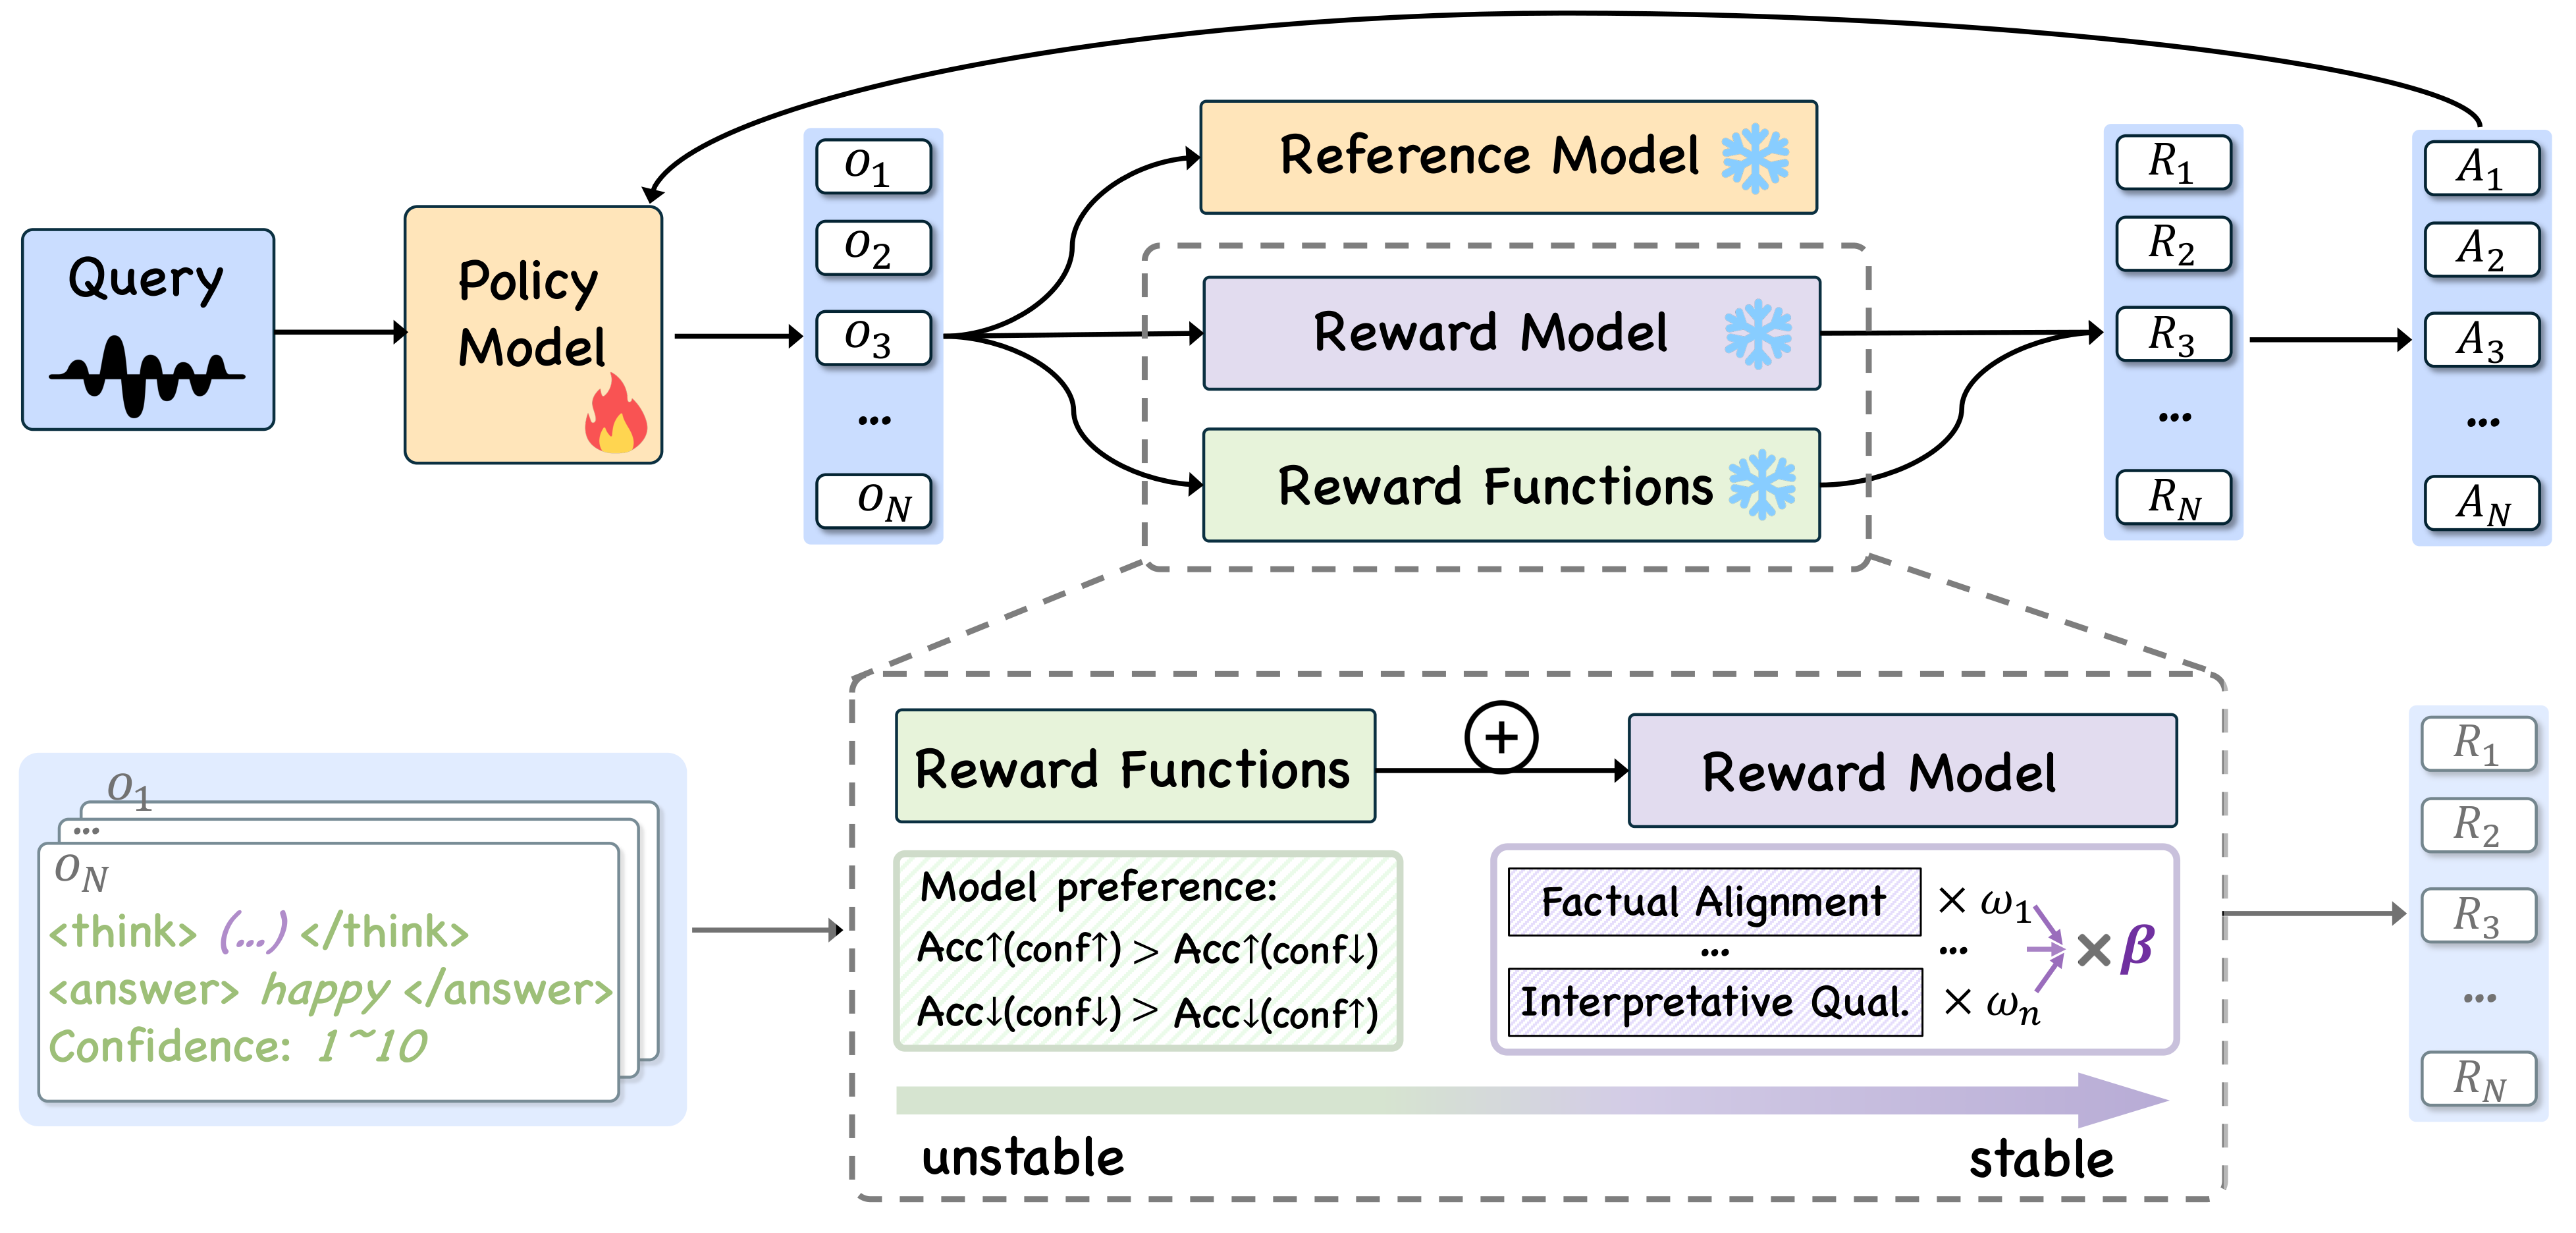
EmotionThinker: Prosody-Aware Reinforcement Learning for Explainable Speech Emotion Reasoning
- First RL-enhanced SpeechLLM for interpretable SER: reformulates speech emotion recognition as deep reasoning.
- GRPO-PTR: progressive trust-aware reasoning reward for RL, improving both accuracy and reasoning quality.
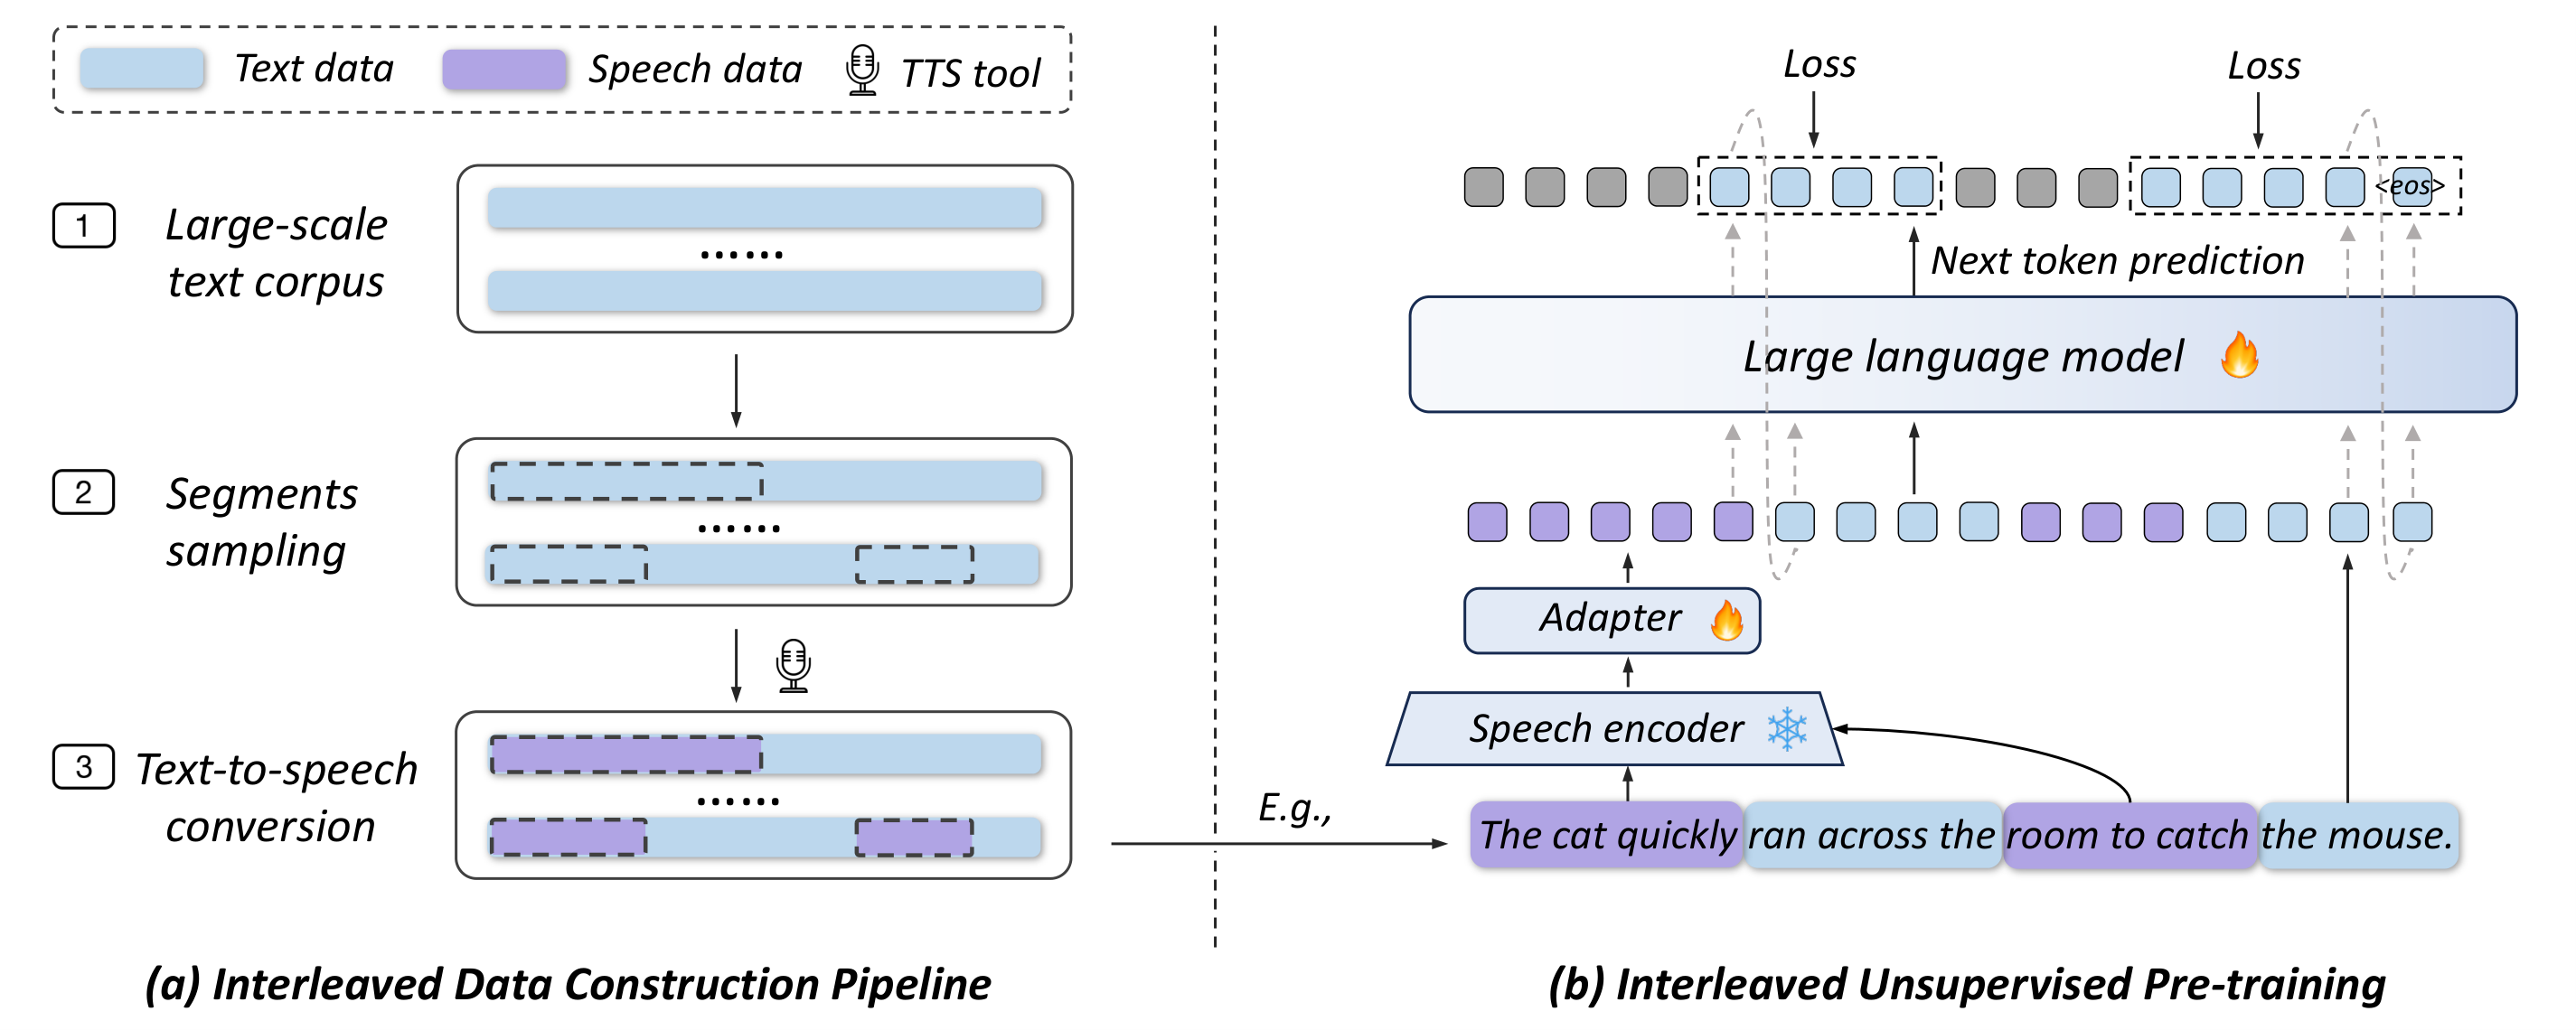
InSerter: Speech Instruction Following with Unsupervised Interleaved Pre-training
- Unsupervised pre-training: interleaved speech-text representation alignment.
- SpeechInstructBench: first speech-oriented instruction following benchmark.
- SOTA performance: + ~10% top-1 accuracy.
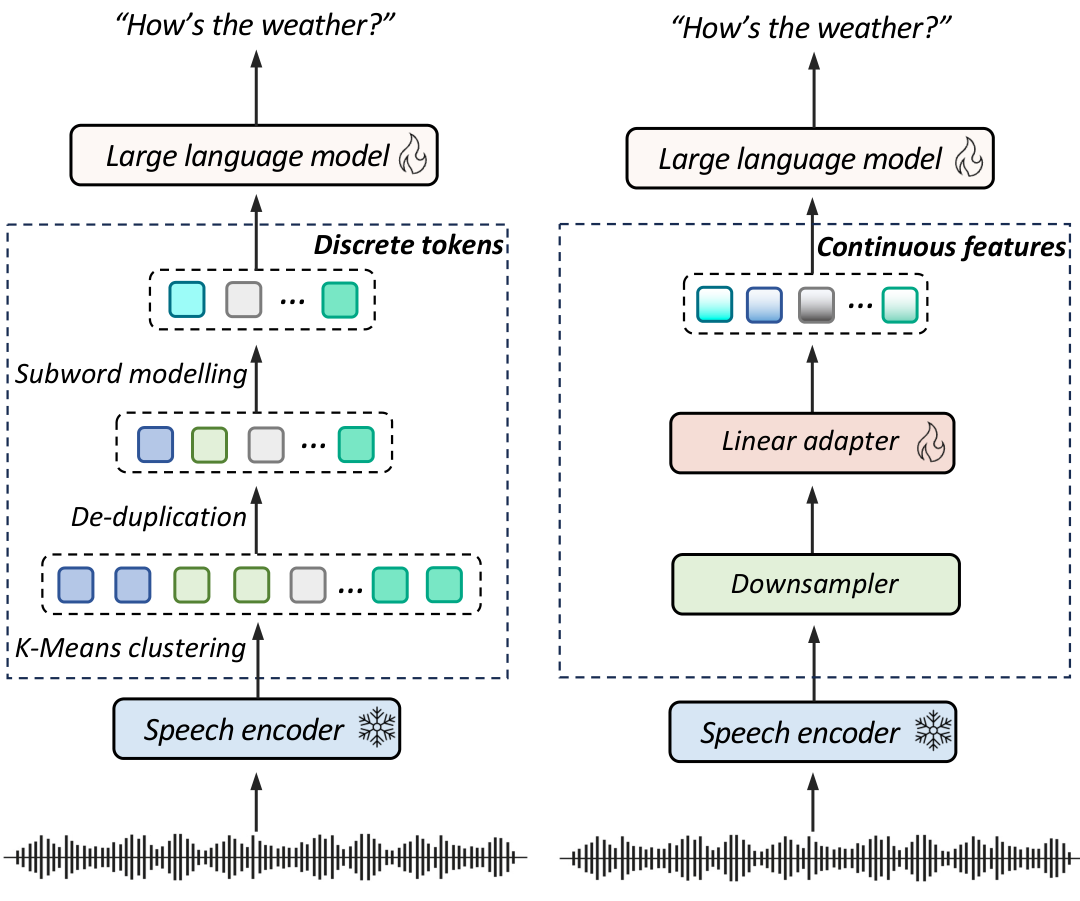
- Controlled comparison: SSL-based discrete vs. continuous features (HuBERT/WavLM) across 6 spoken language understanding tasks.
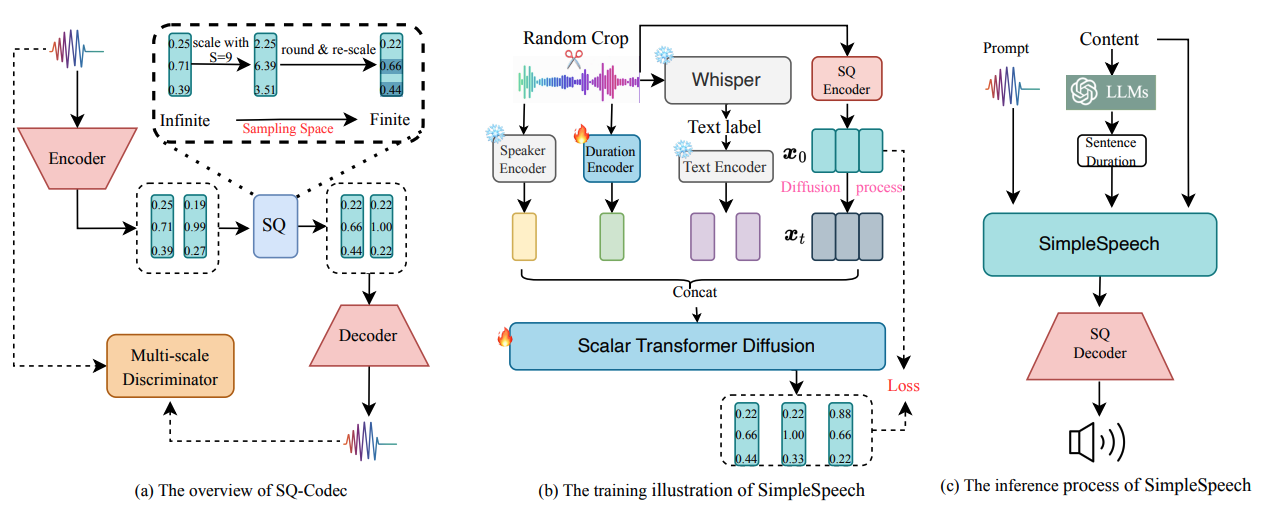
- SQ-Codec: scalar-quantization speech codec mapping audio into a finite, compact latent space.
- Simple and scalable: non-autoregressive, trained on 4k hours of speech-only data with no alignment information needed.
- Significant gains in speech quality and generation speed over prior large-scale TTS models.
📋 Academic Service
Reviewer
- IEEE/ACM Transactions on Audio, Speech, and Language Processing (TASLP)
- Conference on Neural Information Processing Systems (NeurIPS)
- International Conference on Machine Learning (ICML)
- International Conference on Learning Representations (ICLR)
- Association for the Advancement of Artificial Intelligence (AAAI)
- Annual Meeting of the Association for Computational Linguistics (ACL)
- IEEE International Conference on Multimedia and Expo (ICME)
- European Conference on Computer Vision (ECCV)
- International Joint Conference on Artificial Intelligence (IJCAI)